Repository navigation
v6.0.0 beta - #224
Draft
mxriverlynn wants to merge 77 commits into
Draft
v6.0.0 beta#224mxriverlynn wants to merge 77 commits into
mxriverlynn wants to merge 77 commits into
Conversation


han-plugin-builder teaches authors to write for Sonnet 5, Opus 5, and
Fable 5 as checked on 2026-07-31. Opus 5.5 has shipped, and it refuses
reasoning-echo instructions, cannot turn thinking off, reads effort
levels differently, and stops long runs early to report.

Evaluate the whole plugin against the Opus 5.5 article (primary), the
"How we use skills" post, the context-engineering post, and Anthropic's
Opus 5.5 prompting page. Twenty-eight candidates went through
adversarial validation; eighteen change entries survive, in five units:

- Per-model facts: add Opus 5.5 to per-model-authoring.md and its four
  mirrors, extend the reasoning-echo warning, the thinking clause, the
  effort re-test note, and separate vague review limits from a checkable
  bar.
- Long runs and delegation: name the stops an autonomous stretch should
  and should not make without touching collaborative stops, bound
  unbounded steps with a finish line and a task file, check fanned-out
  evidence, and wait for background dispatches.
- Instruction style: a limit on "be specific", a removal bullet for
  instructions restating model defaults, and a gotchas category.
- Baseline skill patterns: verification skills, skill state kept in
  ${CLAUDE_PLUGIN_DATA}, helper-script libraries, and a skill-scoped
  guardrail hook.
- Builder routing: skill-builder and agent-builder read and review
  against the per-model guide.

The operator approved all four behavior-changing decisions. The plan,
its decision log, the current-state findings, and the scope boundary
live in docs/plans/opus-5-5-plugin-builder-guidance/. No plugin file
changes in this commit.
The per-model guide covered Sonnet 5, Opus 5, and Fable 5 as checked on
2026-07-31. Opus 5.5 has shipped with behavior that changes what an
author writes.

- Name Opus 5.5 and state that it inherits the Opus 5 guidance except
  where a section says otherwise, per Anthropic's Opus 5.5 page.
- Extend the reasoning-echo warning to Opus 5.5 and name the
  reasoning_extraction refusal category.
- Note that Opus 5.5, like Fable 5, cannot turn thinking off.
- Tell authors that effort names mean more thinking on Opus 5.5, and to
  re-test a pinned effort value rather than carry it over.
- Keep the warning against vague review limits, and add that a limit
  naming a checkable bar with per-item evidence is fine.
- Add the Opus 5.5 sources and a Contents list.

Mirror the model list in the guidance router, the portable router, the
rule index, and the specialization guide, and point both frontmatter
tables' effort rows at the effort guidance.

Plan: docs/plans/opus-5-5-plugin-builder-guidance (Unit 1, S-1 to S-6).
Opus 5.5 works longer on its own and sometimes ends a turn with a
progress report instead of the next step. The guidance covered
deliberate human gates, but not that.

- workflow-patterns.md: name the stops an autonomous stretch should and
  should not make, and keep the keep-going instruction out of any skill
  built to hand control back. Bound a step that works through an
  unknown number of items with a checkable finish line and a checklist
  file that survives context summarization.
- multi-agent-economics.md: when fanning out, check each subagent's
  cited evidence before accepting its finding, and do not finish while
  a run_in_background dispatch is still running.
- agent graceful-degradation.md: a research or analysis agent marks a
  claim it could not confirm and says where it looked.
- per-model-authoring.md: name Opus 5.5's early-stop behavior and link
  the pattern.
- agent-builder Step 6 item 8 names both degradation rules, and the
  rule index describes the widened files.

The stop-naming section describes collaborative stops rather than
linking han-core's collaborative-stop rule, because this guidance is
vendored into other repos by `guidance init`, where that link would not
resolve.

Plan: docs/plans/opus-5-5-plugin-builder-guidance (Unit 2, S-7 to S-10).
Anthropic's skills and context-engineering posts report that Claude 5
generation models are over-constrained by blanket rules, that
restating default behavior adds tokens without changing output, and
that a gotchas list is the highest-signal content a skill carries. The
guidance pushed toward specificity with no limit, removed only
toolchain-enforced rules, and had no gotchas category.

- writing-effective-instructions.md: spend specificity where a miss
  breaks something, and leave out rules for details the model gets
  right unprompted. The rule governs instruction detail, not whether a
  step is fixed, and links the entity taxonomy's flowchart test.
- progressive-disclosure.md: list instructions that restate model
  defaults as removable, and name gotchas as a reference category.
- skill-reference-files.md: define gotchas as failure points found in
  use, distinct from a checklist or a canonical example.
- Rule index describes the widened files.

Plan: docs/plans/opus-5-5-plugin-builder-guidance (Unit 3, S-11 to S-13).
…s, and skill hooks

Anthropic's skills post describes four patterns the guidance lacked.

- success-criteria-and-testing.md: how to build a skill whose job is
  verifying a running product: pair it with a driver, assert state at
  every step, and record the run.
- plugin-json-options.md: keep a plugin-shipped skill's first-run
  answers and run history in ${CLAUDE_PLUGIN_DATA}, never in the skill
  directory, which ${CLAUDE_PLUGIN_ROOT} replaces on update. Name
  userConfig, hand-edited files, and repo-checked-in skills as the
  cases that need something else. allowed-tools-AskUserQuestion.md
  links to it.
- hardening-fuzzy-vs-deterministic.md: a library of helper functions
  the model composes into one-off scripts, which still prompt for
  permission. Adds a Contents list now that the file is over 100 lines.
- skill-frontmatter-fields.md: a skill-scoped hook lasts only for the
  run, which suits a guardrail such as blocking destructive commands.
- Rule index describes the widened files.

The state section does not say whether saving to ${CLAUDE_PLUGIN_DATA}
prompts for permission, because no source this plan used states it.

Plan: docs/plans/opus-5-5-plugin-builder-guidance (Unit 4, S-14 to S-17).
…r-model guide

Neither builder read per-model-authoring.md or reviewed against it, so
the Opus 5.5 guidance reached only people who asked the guidance skill
directly.

- Both decision tables route "instructions for a named target model"
  to per-model-authoring.md.
- Both Step 6 reviews gain a model-specific-leftovers item: no "think
  step by step" line, no instruction to reproduce reasoning in the
  reply, no pinned effort without a stated reason, and no vague
  limiting phrase in a review step, with one passing and one failing
  example quoted.
- skill-builder's progressive-disclosure item also cuts instructions
  that restate a default the model already follows, matching the
  guidance change in progressive-disclosure.md.

Also rewraps the specialization guide's per-model cross-reference,
which the Opus 5.5 addition pushed past 120 characters.

Plan: docs/plans/opus-5-5-plugin-builder-guidance (Unit 5, S-18).
…ection

Found by the /han-update-documentation pass over the branch.

…lder docs

The skill-builder and agent-builder long-form docs now say the review pass
strips model-specific leftovers and that per-model authoring is a governing
document in the design-tree map, matching the SKILL.md changes on this branch.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>

check-cross-references.sh and check-plan-cross-references.sh find an entry's
heading in awk with the interval expression #{2,4}. mawk 1.3.4 20240123, the
default awk on Ubuntu 24.04, matches only two hashes with it, so the
"### F1:" and "### D-1:" headings the templates produce are never read.

On that awk a valid review fails with empty-field for every finding, and a
decision log that cites a plan section the plan does not have passes. Eleven
of the two scripts' Bats tests fail there; CI runs gawk, so it stays green.

Spell the level as ###?#?, which every awk reads the same way, and add a
four-level heading test to each suite.
…ops-engineer and on-call-engineer
…minimal tools, data-engineer reverse boundary)
…lls, and gap-analysis dispatch
…skill doc updates
Adds `han-core:observability-engineer`, an adversarial reviewer for
telemetry design, and wires it into every skill that routes
observability today.

## Why

Research
([docs/research/observability-engineer-research.md](docs/research/observability-engineer-research.md))
found that Han already covers most of observability. `devops-engineer`
owns SLOs, burn-rate alerting, dashboards, and the golden signals.
`on-call-engineer` owns source-line debuggability, correlation IDs, and
PII in log statements. What nobody owns is the design layer between
them: how telemetry is named, metric label cardinality and what it
costs, whether sampling keeps the error and slow traces, and how the
telemetry pipeline is configured. Those problems fall between the two
reviewers at both the code and configuration levels.

Adversarial validation narrowed the recommendation from a broad
observability owner to this telemetry-design slice. The broad version
would have rewritten two working agents.

## What changed

- **New agent:** `han-core/agents/observability-engineer.md`
  - `opus`, read-and-report only.
  - Content: 9 named anti-patterns, 7 protocols, `OBS-###` findings.
- Names both the metrics-first and events-first schools and recommends
whichever fits the existing stack.
  - Carries a YAGNI guard for small, low-traffic services.
- **Two-way boundaries:** `devops-engineer`, `on-call-engineer`, and
`data-engineer` each point back to the new agent. The `on-call-engineer`
and `data-engineer` descriptions were trimmed to stay within the
1024-character budget.
- **Dispatch wiring:** code-review, architectural-analysis,
iterative-plan-review, plan-a-feature, plan-a-change,
plan-implementation, and gap-analysis. Each gets a selection signal, a
scoped brief, and a report or plan section.
- **Docs:** long-form doc
`han-core/docs/agents/observability-engineer.md`, the `han-core` README
line, the agents index, the sibling agent docs, and the roster docs.

## Not in this PR

- No CHANGELOG entry or version bumps; `/han-release` owns those.
- Pre-existing issues I left alone:
- Sentence fragments below the opening paragraph of
`on-call-engineer.md` and `devops-engineer.md`.
- architectural-analysis never lists `OCE-###` in its verbatim-ID step.

## Testing

- `npm test`: all 121 tests pass.
- `npm run lint`: all non-formatting hooks pass, and Prettier is clean
on every changed file.
- Lint also reformats existing `evals/` files on `main`. I reverted
those changes, so they are not in this PR.

**Open check:** the research's reopen trigger still applies. Run the
agent on a few real telemetry changes. If it finds nothing
`devops-engineer` and `on-call-engineer` would not, fold its checks into
`devops-engineer`.
…aits on the operator
… fold in review round findings
… from the skill

Merges the signal and file-list slice tables into one roster table with output-file and
series columns, points Step 7.1 and verification item 2 at it, and replaces each prompt's
"Write your output to" with a hand-back sentence the skill files from (S-1, S-2, S-31).
… rule

Deletes the size classifier and every size reading, drops a lone retired size word with a
one-line note, puts the default severity rule in the Step 3.3 calibration directive for
manual and agent findings alike, and stops code review reading default-swarm-size
(S-3, S-4, S-20, S-25 size wording).
This PR proposes making the plan cross-reference checks read `###` and `####` entry headings under mawk, the default awk on Debian and Ubuntu. We include this PR work along with a full history of your repo at https://eastagiletracker.com/projects/798. You can sign in with your GitHub ID to claim ownership of the project. `check-cross-references.sh` (run by `iterative-plan-review`, SKILL.md step at line 422) and `check-plan-cross-references.sh` (run from `plan-implementation`'s `step-9-checks.md`) locate an entry's heading inside awk with the interval expression `#{2,4}`. mawk 1.3.4 20240123, which is `/usr/bin/awk` on a stock Ubuntu 24.04, matches only two hashes with that form, so the `### F1:` and `### D-1:` headings the review-findings and decision-log templates produce are never recognized. The two scripts then fail in opposite directions: a valid review pair fails with `empty-field` for every finding, and a decision log whose `Referenced in plan` names a section the plan does not have passes, because the field is never read. CI stays green because the runner's awk is gawk. Reproduced on current `main` (abba73a), Ubuntu 24.04 with its default awk: ``` $ awk -W version | head -1 mawk 1.3.4 20240123 $ printf '### F1: x\n' | awk '/^#{2,4} /{print "matched"}' (no output) $ check-cross-references.sh f.md h.md # valid pair, "### F1:" as in review-findings-template.md result: failed empty-field: F1 Raised in round empty-field: F1 Changed in plan $ check-plan-cross-references.sh plan.md log.md hist.md # "### D-1:" cites "Nonexistent Section" result: passed ``` The fix spells the level as `###?#?`, which is the same set of headings (two to four hashes, five or more still excluded) and which every awk reads the same way. Each Bats file gains a four-level heading test; both fail against the unfixed scripts under mawk and pass with the fix. `npm test` on `main` under mawk: 109 ok, 12 not ok, all in these two suites. Eleven of the twelve are this defect. With this branch: 122 ok, 1 not ok. The remaining failure, "an unreadable plan is unverified", fails the same way before and after because the run was as root, and root can read a mode-000 file. Under gawk 5.2.1 both suites give the same result before and after, so nothing changes on the platform CI uses. `prek` passes on the four changed files. ## How this was managed This fix was tracked as story https://eastagiletracker.com/projects/798/stories/1044085 on a board imported from this repo's issues and pull requests (197 stories), at https://eastagiletracker.com/projects/798. 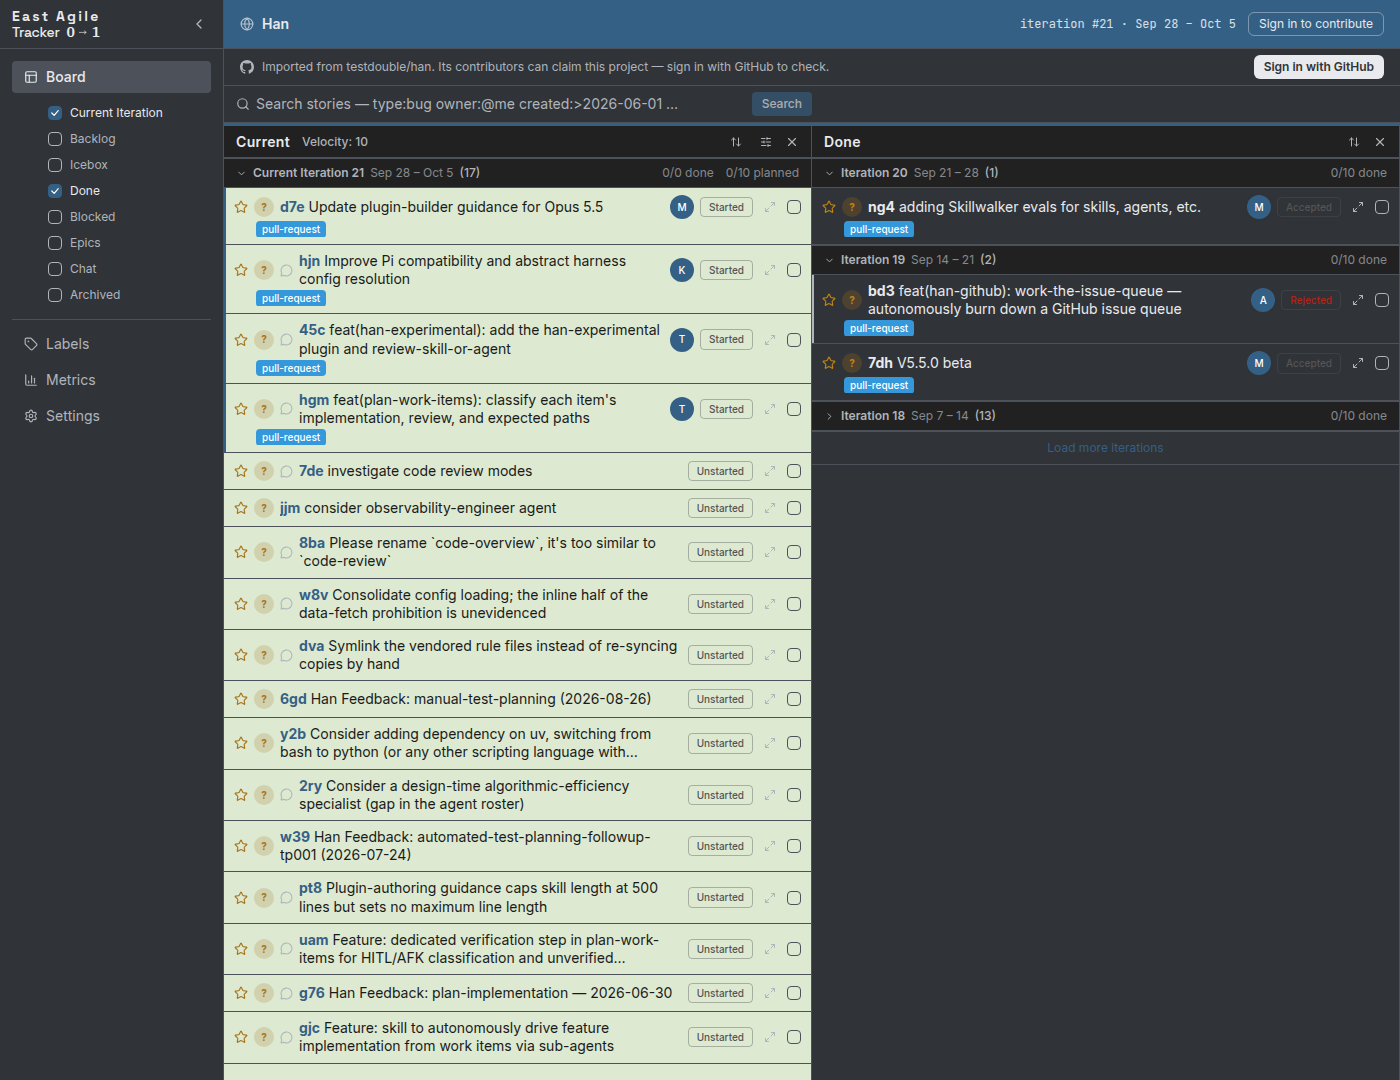 If you'd rather not receive contributions like this, reply `no-more-prs` on this pull request and we won't open any further ones on your repositories. --- **Lawrence W. Sinclair** CEO / East Agile [linkedin.com/in/lwsinclair/](https://linkedin.com/in/lwsinclair/) [eastagile.com](https://eastagile.com)
v0.11.0.1-1 ships the same ShellCheck 0.11.0 and only raises the hook's
floor to Python 3.10. prek resolves macOS's system Python 3.9, so the
bump breaks lint locally while adding nothing.
## Summary

Moves the dev tooling to the latest versions that work here, across the
three ecosystems Dependabot tracks: npm, GitHub Actions, and pre-commit
hooks.

| Dependency | From | To |
| --- | --- | --- |
| `prettier` | 3.9.6 | 3.9.10 |
| `@j178/prek` | 0.4.11 | 0.5.5 (crosses a 0.x minor) |
| `bats` | ^1.11.1 | ^1.13.0 (floor raised to match the lockfile; the
installed version is unchanged) |
| `actions/setup-node` | v7.0.0 | v7.1.0 |

The rest were already on their latest releases: `actions/checkout`
v7.0.1, `actions/cache` v6.1.0, and `pre-commit-hooks` v6.0.0.

**`shellcheck-py` stays on v0.11.0.1 on purpose.** The newer
`v0.11.0.1-1` tag ships the same ShellCheck 0.11.0. Its only change is
requiring Python 3.10 or later. prek uses macOS's system Python 3.9, so
on a stock Mac the hook fails to install and `npm run lint` breaks. The
branch has the bump and its revert as separate commits.

**Cooldown note:** `.github/dependabot.yml` holds each new release for
30 days. Several of these are newer than that: prek 0.5.5 (Oct 5),
Prettier 3.9.10 (Oct 10), and setup-node v7.1.0 (Oct 8). Merging this PR
gets around the cooldown for those three.

The eval scaffold `package.json` files under `evals/` are test fixtures,
so they were left as they are.

## Key file changes

- `package.json`, `package-lock.json`: npm devDependency upgrades.
- `.github/workflows/ci.yml`: `actions/setup-node` v7.1.0 in both jobs.

## Test Plan

- [x] `npm run lint` passes on every hook locally.
- [x] `npm test` runs every Bats test with 0 failures.
- [x] CI lint and test jobs pass on this PR.

…nd expected paths

Enrich the producer so each work item carries the markers the downstream
driver needs, without pulling in the driver itself:

- Add a Type field (deliverable / audit / spike) and rename Tests -> Checks
  in the work-item template.
- Add Suggested implementation, Suggested review, Requires pre-work decisions,
  and Expected paths fields, selected via a new deliverable-skill catalog.
- Direct project-manager to derive those markers and expected paths, and close
  the run with the three-bucket (unattended / pauses-for-human) recommendation.
- Reframe the upstream unverified-assumptions guidance onto Requires pre-work
  decisions, since item-level HITL/AFK moves to the per-marker model.

Split out of feat/autonomous-driver-core-loop as a standalone producer-side
change; carries no implement-work-items edits.

Rebased onto v6.0.0-beta, resolving conflicts with the reworked skill:

- The breakdown is now dispatched to plan-synthesizer, not project-manager;
  the new directives sit beside the Justification and drafting-order ones.
- v6 removed the separate Tests block, so there is no Checks block; the
  audit and spike check guidance moved into Acceptance criteria.
- Summary stays first; the classification fields (Type, Requires pre-work
  decisions, Suggested implementation/review, Expected paths) render after
  Acceptance criteria and before Depends on.
- Catalog skill namespaces updated for skills that moved out of han-core
  (han-documentation, han-research).
- Long-form doc changes ported to han-planning/docs/skills/plan-work-items.md;
  links to the not-yet-merged implement-work-items doc dropped.

Co-Authored-By: Claude Opus 4.8 (1M context) <noreply@anthropic.com>
Co-Authored-By: River Bailey <river.bailey@testdouble.com>
Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01BvgX88kC9h9xbe4zGLf7BC
…nd expected paths (#226)

Replaces #111 by @taminomara, rebased onto `v6.0.0-beta` to resolve its
merge conflicts. The original branch lives on a fork we can't push to,
so this PR carries the same commit with @taminomara kept as the commit
author. All credit for the change is theirs.

## What the change does

`plan-work-items` now records, for each work item, which skill or agent
should build it and which should review it, and whether each part can
run unattended (`AFK`) or needs a human (`HITL`). Each item also records
a `Type` (`deliverable`, `audit`, or `spike`), whether it needs a human
decision before work starts, and the files it is expected to touch. A
new deliverable-skill catalog maps each kind of deliverable to its
suggested implementation and review.

## How the conflicts were resolved

The skill changed a lot on `v6.0.0-beta` since #111 was opened, so the
resolution adapts the change to the new shape rather than replaying it
line for line:

- The breakdown is now drafted by `plan-synthesizer`, not
`project-manager`. The new directives sit beside the existing
justification and drafting-order directives.
- `v6.0.0-beta` removed the separate `Tests` block, so there is no
`Checks` block. The audit and spike check guidance moved into
`Acceptance criteria`.
- `Summary` stays first. The classification fields (`Type`, `Requires
pre-work decisions`, `Suggested implementation`, `Suggested review`,
`Expected paths`) render after `Acceptance criteria` and before `Depends
on`.
- Catalog skill names updated for skills that moved out of `han-core`
(`han-documentation:*`, `han-research:research`).
- Long-form doc changes ported to its new home,
`han-planning/docs/skills/plan-work-items.md`. Links to the
`implement-work-items` doc were dropped, since that skill isn't in this
repo yet; `SKILL.md` still offers it only when it is available.

## Open from #111

The original PR was a draft, and @taminomara noted `audit` and `spike`
were meant to merge into one type before it was ready. That is still
open, so this PR is also a draft.
…ilder

Checks the plugin-builder guidance against Anthropic's current pages for
Opus 5.5, Sonnet 5.5, Haiku 5.5, Fable 5.1, and Claude Code's model
settings, with adversarial validation.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…-model guide

- Widen the reasoning-echo section to every current model and list the
  four trigger shapes, including a reasoning field in an output format
- Scope the cut-verification advice to Opus; Sonnet 5.5 and Haiku 5.5
  skip checks at low effort and need the instruction kept
- Add Claude Code's thinking and effort defaults for the 5.5 models
- Add early-stop and scope habits for Sonnet 5.5 and Haiku 5.5
- Quote the Fable claim as Anthropic words it; fix the review-prompt
  attribution to the blog post

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
- Subagent model order is now dispatch, frontmatter, env var, main
  model (v2.1.251+), with CLAUDE_CODE_SUBAGENT_MODEL_FORCE to override
- An omitted model is not the same as inherit
- Add the fable alias; note that aliases resolve by provider
- Explore now runs on the main session's model; link the live table
- Note Haiku 5.5's subagent fit and its low-effort habits

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…he 5.5 models

- Builders' model-specific review check now flags a reasoning, thinking,
  or trace field, a scratchpad section, or a running reasoning log
- Name model families instead of a fixed four-model list in the guidance
  skill, its portable copy, the rule index, and the specialization guide
- Replace an unsourced Haiku claim in the testing guide with the
  documented Haiku 5.5 behaviors

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
- Move the two Anthropic links off the old docs hosts to their current
  platform.claude.com pages
- Re-quote both Anthropic passages from the current wording; the old
  quotes no longer appear on either page
- Say thinking depth rather than thinking budget, since budget_tokens is
  gone on the 5.5 models
- Point the dead Deepgram link at its Wayback Machine snapshot

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
## Summary

**This PR updates the `han-plugin-builder` authoring guidance and its
two builder skills for the Claude 5.5 models (Opus 5.5, Sonnet 5.5,
Haiku 5.5, and Fable 5.1), so that new skills and agents stop carrying
instructions that current models refuse, ignore, or no longer need.**

## Behavior changes

The main runtime change is in `skill-builder` and `agent-builder`. Both
now send authors to the per-model guide (`per-model-authoring.md`)
whenever a target model comes up. Their final review (Step 6) has a new
item that catches leftovers tied to a specific model. It flags "think
step by step" lines, any request that the model reproduce its reasoning,
and output formats with a `reasoning`, `thinking`, or `trace` field, a
scratchpad section, or a running reasoning log. Every current model now
refuses that kind of request, which shows up as a `reasoning_extraction`
refusal, so the check is no longer limited to Fable 5 and Opus 5.5. The
item also flags a pinned `effort` value with no stated reason, and vague
review limits such as "only report high-severity issues." A limit passes
when it names a bar the reader could check and asks for evidence on each
item.

Two existing review items are stricter. `agent-builder` now requires a
research or analysis agent to mark each claim it could not confirm and
say where it looked. `skill-builder` now counts an instruction that
restates something the model already does by default as removable.

The rest of the branch is guidance text that the builders and
`/guidance` read:

- **Per-model facts.** Advice to cut verification instructions applies
only to Opus. Sonnet 5.5 and Haiku 5.5 skip checks at low effort.
- **Subagent model choice.** The order Claude Code uses to pick a
subagent's model changed in v2.1.251. Explore no longer runs on Haiku.
- **Long runs and fan-out.** New patterns for unattended work and for
fanning work out to subagents.
- **Other new sections.** Verification skills, where skill state lives
(`${CLAUDE_PLUGIN_DATA}`), helper-script libraries, and hooks scoped to
one skill's run.

All model facts come from Anthropic's own docs, checked 2026-10-15. The
planning and research behind each change are in
`docs/plans/opus-5-5-plugin-builder-guidance/`. Repos that vendored this
guidance with `/guidance init` get it on `/guidance update`, so mention
that in the release notes. The branch also carries one unrelated note,
`docs/plans/fix-ci-lint-evals-prettier/investigation.md`, which
investigates a CI lint failure.
The red-step revert restored touched files from git whenever the tree was
clean at the start of the run. Commits during a run are optional, so a
restore reset a shared file to its last commit and discarded earlier green
steps that were not yet committed. Undo the step's own edits directly and
never use checkout, restore, reset --hard, clean, or stash to undo a step.

Co-Authored-By: Claude <noreply@anthropic.com>
## Summary

The refactor skill's red-step revert could throw away finished work.

**The bug.** On a red suite, the skill ran `git checkout`/`git restore`
on the touched files whenever git was available and the tree was clean
*at the start of the run*. Commits during a run only happen if you ask
for them, and even then can be grouped. Git restores a file to its last
commit, so when two steps touch the same file with no commit between
them, reverting the second step also discarded the first, already-green
step. That contradicted the skill's own stop-rule promise that
"everything already applied is green and stands."

**The fix.** A red step now undoes only its own edits directly: reverse
each edit, delete any file the step created, and move renamed or moved
files back. The skill never restores files from git to undo a step,
never runs `git reset --hard`, `git clean`, or `git stash` for it, and
re-runs the suite to show the revert is back to green.

## Changes

- `han-coding/skills/refactor/SKILL.md`: Step 4, item 4 rewritten.
- `han-coding/docs/skills/refactor.md`: the "what you get" bullet now
says a revert touches only that step's edits.

Found during the Mikado Method research in #228. That research's Mikado
recommendations are deliberately out of scope here.

## Test plan

- [x] `npm run lint` passes
- [x] `npm test` passes
- [ ] Manual: run `/refactor` on a target where two planned steps edit
the same file, with no commits requested, and force the second step red;
confirm the first step's change survives the revert.

🤖 Generated with [Claude Code](https://claude.com/claude-code)
Han's review loops could only say 'this finding, this fix'. A plan that kept drawing edge-case findings on one mechanism ran to its round cap while being patched, and nothing asked whether a different tool or shape would make the whole class of findings moot. The investigation is in docs/plans/review-loop-approach-reassessment/investigation.md.

Add /reassess-approach: it gathers a plan or code unit, its recorded findings, and the reason it is asked, dispatches one han-core:software-architect critic in a fresh context, and returns structurally different alternatives, always including stop and continue, as one options report and one question. iterative-plan-review (team mode) and plan-implementation (medium and large) invoke it at their round cap when the convergence condition still fails; small runs end with a pointer instead. Docs, catalogs, and an eval suite with a regex-parser fixture are included. Plugin versions and the changelog are untouched.

Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
…r stalled units

Coordinates architectural-analysis, plan-a-change (or its own plan when
han-planning is absent), and refactor or tdd per unit, after one start
gate. A unit that stalls becomes the goal of a Mikado graph: attempt,
record prerequisites, undo with undo-attempt.sh, and work leaves first.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…d workflow map

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…ap (#231)

## Summary

Han's review loops could only say "this finding, this fix". A plan that
kept drawing edge-case findings on one mechanism ran to its round cap
while being patched, and nothing ever asked whether a different tool or
shape would make the whole class of findings moot. The investigation
behind this change is in
`docs/plans/review-loop-approach-reassessment/investigation.md`.

This PR adds `/reassess-approach` to `han-planning`. It gathers a plan
or code unit, the findings it has absorbed, and the reason it is being
asked, then dispatches one `han-core:software-architect` critic in a
fresh context with only that material. The critic returns structurally
different alternatives, always including "stop doing this" and "continue
as is", each citing the recorded findings it would make moot, what it
adds and removes in owned code paths or plan items, and what to run
next. The skill writes one options report and changes nothing; the
decision comes back to the person as one question.

`/iterative-plan-review` (team mode) and `/plan-implementation` (medium
and large) invoke it when they reach their round cap without converging,
record the result as an `approach` finding or ledger tag, and present
the options through their existing question channel. Small runs, capped
at one round, do not hand off: one pass cannot tell a plan stuck on its
approach from a plan that needed edits, so they end with a one-line
pointer to the skill instead. The skill is also invocable by hand on any
plan or code path.

## Key file changes

- `han-planning/skills/reassess-approach/SKILL.md` and
`references/approach-reassessment-template.md`: the new skill and its
report template.
- `han-planning/skills/iterative-plan-review/SKILL.md`: `approach` as a
major category, the team-mode hand-off at the cap, the lightweight
pointer, and the closing-question wording.
`references/review-findings-template.md` gains the category and an
`Alternatives:` field.
- `han-planning/skills/plan-implementation/SKILL.md` and
`references/round-aggregation.md`: the facilitation-plateau note becomes
the hand-off at medium and large, with an `approach` ledger tag.
- `han-planning/skills/plan-a-change/SKILL.md`: reverse boundary clause
so disambiguation runs both ways.
- `han-planning/docs/skills/reassess-approach.md`, plugin README, skills
index, `docs/workflows.md`, `docs/concepts.md`, `docs/readability.md`,
`docs/yagni.md`, `docs/evidence.md`, `CLAUDE.md`, `CONTRIBUTING.md`, and
the `software-architect` agent doc: documentation and catalog coverage.
- `evals/reassess-approach/`: five trigger tests and one functional test
over a scaffold with a hand-written regex parser, a plan that commits to
it, and three rounds of clustered edge-case findings.

Plugin versions and `CHANGELOG.md` are untouched. Manifest descriptions
list the new skill.

## Test Plan

- [x] `npm run lint` passes on every tracked file touched; a direct
`prettier --check` passes on the new files.
- [x] `npm test`: the suite could not complete in the authoring sandbox
(its temp directory is unwritable). The branch changes no shell script
or `.bats` file, and the suite passed 121/121 on this branch before the
final Markdown-only edits. Please run it once locally.
- [x] Run the `evals/reassess-approach` suite. The functional case is
the first measurement of whether the critic's alternatives are
structurally different rather than nearby variants.
- [ ] Run `/iterative-plan-review large` over a plan whose findings file
is at the cap and confirm the closing question carries the options.

🤖 Generated with [Claude Code](https://claude.com/claude-code)
…and plan-a-change to it

Adds restructure to pairing's flagged skills and to the collaborative-stop
rule (canonical and both vendored copies, still byte-identical), and gives
refactor and plan-a-change routing lines toward restructure.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Moves the missing-test-command case out of the hard-failure list and into
the start gate, says what happens when a Mikado leaf stalls, and renames
the test fixture's folder so no conventional source path appears.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
# Conflicts:
#	docs/concepts.md
#	han-planning/skills/plan-a-change/SKILL.md
…232)

## Summary

**This PR adds a `restructure` skill that reorganizes a codebase toward
a target layout one committed unit at a time, so that a large
restructure can run unattended without changing behavior.**

## Behavior changes

The new `han-coding:restructure` skill coordinates the work and leaves
the code changes to existing skills. You state a goal, such as "group
each package by feature." The skill discovers the project's layout,
commands, test roots, and documented structure rules at runtime, so it
works on any codebase. It shows all of that at one start gate and then
asks nothing further. After you confirm, it runs
`architectural-analysis`, plans ordered units, and hands each unit to
`refactor` or `tdd`. Each green unit is committed on the current branch,
and every decision goes into a change log with its justification. The
skill never pushes, never switches branches, and never edits a test to
make a unit pass.

When a unit stalls because its code is too tangled to move in one step,
the skill switches to the Mikado Method. It tries the change, records
what breaks as prerequisites in a graph committed to the repo, undoes
the attempt, and does the prerequisites first. A bundled
`undo-attempt.sh` script restores the tree to the last commit. It
refuses to run if HEAD has moved, and it removes only untracked files
that git does not ignore, which is why the skill requires a clean tree
at the start. Discovery stops after five rounds per stalled unit by
default; the unit is then logged as not done and its dependents are
skipped.

Three existing skills route work differently. `pairing` can now drive
`restructure`, stopping after each unit so you can review the commit.
The descriptions of `refactor` and `plan-a-change` now point to
`restructure` for whole-area work. `han-coding` gains no dependency on
`han-planning`: when `plan-a-change` is not installed, `restructure`
writes the unit plan itself and records that in the change log. The
research report behind the design is included at
`docs/research/mikado-method-skill.md`.
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
Sign up for free
to join this conversation on GitHub.
Already have an account?
Sign in to comment



Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.
v6.0.0 Beta
install:
/marketplace add git@github.com:testdouble/han#v6.0.0-beta/plugin install ha@han- or any other specific Han pluginIncludes the following: